
a good ship from Qwen.
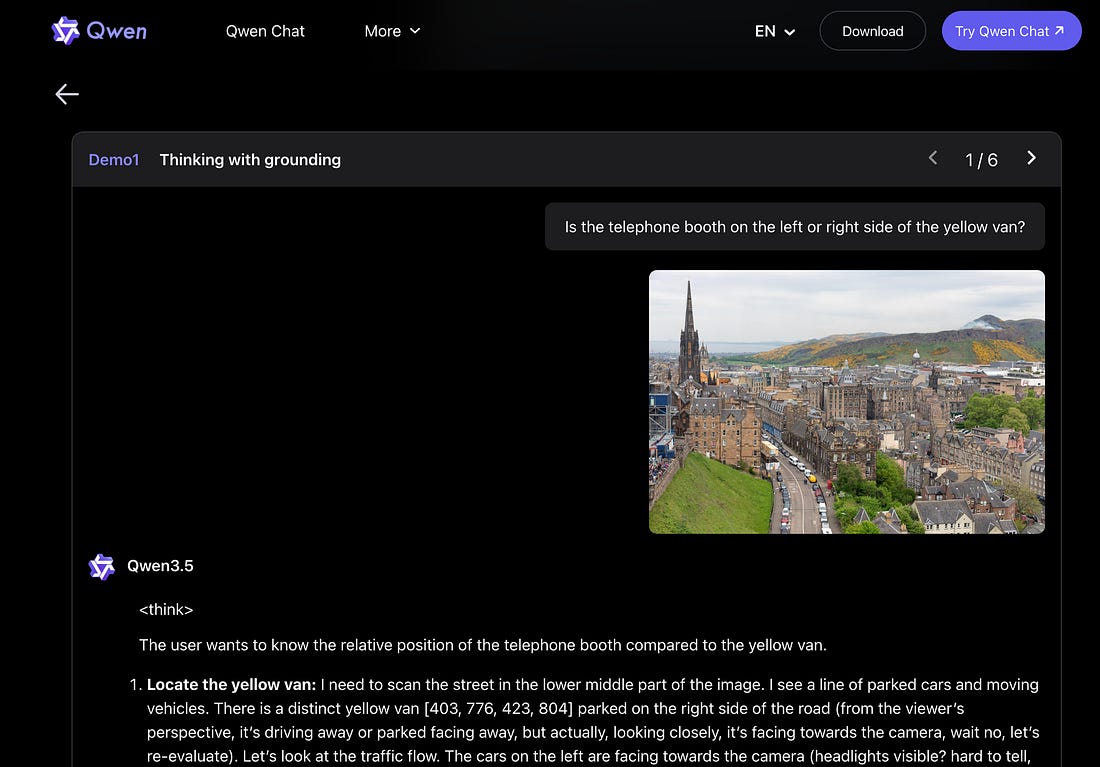
Congrats to Pete Steinberger on joining OpenAI, as we predicted. Not much else to add there so we won’t. Today’s headliner is Qwen 3.5, which followed the other Chinese model labs like Z.ai and Minimax and Kimi in refreshing their leading models, but unlike the first two, Qwen 3.5 is in the same weight class as Kimi, 400B with about a 4.3% sparsity ratio instead of Kimi’s more agressive 3.25%. They do not claim SOTA across the board, and most notably not across coding benchmarks, but make solid improvements compared to Qwen3-Max and Qwen3-VL. Native Multimodality and Spatial Intelligence are headline features of the model and we encourage clicking over to the blog to check out the examples, as there isn’t much else to say - this is a very welcome headline model refresh from China’s most prolific open model lab, and probably the last before DeepSeek v4.
AI Twitter Recap...Keep reading with a 7-day free trialSubscribe to Latent.Space to keep reading this post and get 7 days of free access to the full post archives. A subscription gets you:
|
[AINews] Qwen3.5-397B-A17B: the smallest Open-Opus class, very efficient model
Monday, 16 February 2026




Subscribe to:
Post Comments (Atom)


No comments:
Post a Comment